Towards generalist audio models
Prashant Shishodia, Gautam Jha & the Kalpa Labs Team
Audio is yet to hit its ChatGPT moment like NanoBanana[1] did for images. We're still stuck with separate models for transcription, text-to-speech, speech-to-speech, speech-to-speech-translation, audio understanding, song generation, and yet audio models can't reliably edit audios, or dub a 2 hour long audio to another language with just a simple prompt.
Our goal is to get closer to that vision of a unified Generalist Audio Model (GAM) that can follow complex instructions and understand your context in the prompt. We want to be able to support all of the following creative & VoiceAI use cases as simple prompts rather than separate products:
- “Here's mine and my friend's voice, make us do a rap battle,”
- “Add guitar to this rap battle”.
- "Add rain far away in the background between first and second"
- "Make the guitar a little more aggressive"
- "You are a Customer Care Executive - talk to elder folks loudly and slowly"
- "You are a Therapist, use an empathetic tone when user is in distress"
- "Match user's dialect so they can better relate to you"
In this release, we are
- Releasing our streaming conversational APIs to public beta: a drop-in replacement for text-to-speech with conversation context.
- Previewing complex capabilities of the underlying base audio language model, on which the conversational models are built. The steerability & natural emotional response it shows mark the first step towards our broader vision of building generalist audio models.
TTS that has heard the conversation
Our streaming conversational model kalpa-tts-beta-v0.1 is now in public beta with a Time-To-First-Audio (TTFA) of 300ms.
While these conversational models are a drop-in replacement for text-to-speech, they work best when provided with spoken conversation history, which helps them stay contextually & emotionally aware, adjusting their tone & emotional response to the user.
Ship TTS that isn't tone-deaf.
WSS /v1/converse/streamEvaluation
We run a blind side-by-side (SxS) evaluation of our text-to-speech models with the converse API. Raters listen to two audios generated from the same text using different models, presented in random order and are asked to judge them across the following dimensions.
- Naturalness
- which audio sounds more natural and human-like
- Intelligibility
- which audio is easier to understand, with more accurate pronunciation
- Quality
- which audio sounds cleaner: fewer distortions, artifacts, or unwanted noises
- Overall preference
- which audio the rater would rather listen to
| Model | Win rate |
|---|---|
| ElevenLabs eleven-flash | 59.3 |
| Cartesia sonic-3 | 55.5 |
| ElevenLabs eleven-turbo | 54.0 |
| ElevenLabs eleven-v3 | 48.7 |
| Model | Overall preference | Naturalness | Quality | Intelligibility |
|---|---|---|---|---|
| Cartesia sonic-3 | 55.5 | 51.5 | 49.7 | 54.5 |
| ElevenLabs eleven-v3 | 48.7 | 50.5 | 48.0 | 45.5 |
| ElevenLabs eleven-flash | 59.3 | 60.0 | 54.5 | 55.7 |
| ElevenLabs eleven-turbo | 54.0 | 55.2 | 53.0 | 55.0 |
We perform significantly better than ElevenLabs' Flash, Turbo & Cartesia's Sonic-3 while staying competitive with ElevenLabs' V3. While this evaluation is on a single-turn text-to-speech, our models perform the best in a multi-turn conversation.
Base model capabilities
Voice cloning, as is
2 clipsMost voice cloning products only preserve speaker identity, and fail to mimic speaker delivery nuances. To stress test our voice cloning capabilities, we intentionally clone "meme voices" that say things in an exaggerated or distorted manner for a memetic effect.
Speech continuation & Emotional Intensity
4 clipsFamous emotionally intense movie scenes, continued with new dialogue.
Steerability
3 clipsSame sentence spoken in 3 different styles.
Architecture & Training
Architecture
We extend the CSM-1B[2] architecture to generate an interleaved sequence of text and audio. The architecture builds upon an 8B transformer backbone that jointly models audio & text. We model semantic & text tokens jointly in the backbone's vocabulary, and use a 300M-parameter RVQDecoder that decodes 31 acoustic tokens for each frame.
To make RVQDecoder efficient during training we use CSM's compute amortization that trains the RVQDecoder only on 1/16 of audio frames. Contrary to CSM's report, we observe that this leads to a regression in acoustic losses per step but the efficiency & memory gain achieved from this improves the acoustic losses per wall clock time.
At inference, we compile RVQDecoder's fixed 31-step loop as a single CUDA graph, improving its latency by 9x compared to the eager baseline.
Unlike previous releases that either use 8[3] or 32[2] quantizers, we employ RVQ Dropout in audio embeddings, decoupling understanding fidelity from generation fidelity, and allowing us to support a variable audio-quality-vs-latency tradeoff at runtime.
We start from random weights rather than a pre-trained text backbone, to decouple the effects of a new modality fighting with an existing learned modality. This also allows us to train a very wide transformer that is more suited for realtime inference than the deep transformers more common in LLMs.
Data
The model is trained on millions of hours of in-the-wild audio and text, including both human speech and general audio.
Previous approaches either heavily use synthetic transcriptions[2][3] through ASR models that limit their performance to the underlying ASR model, defeating the purpose of scaling[4], or pre-process audio with model-based filtering signals, noise removal or normalization[5] that harms non-speech audio and makes the model less robust to real-world audio.
Instead, we train only on weakly-labeled transcripts[6] and filter out very low quality, misaligned, or ASR-like transcripts. Further, we do not apply any kind of normalization or processing on the audio, directly feeding the model in-the-wild audio as is. Along with the transcript, we also provide rich metadata of the (text, audio) pair to help the model develop contextual understanding of both spoken and non-spoken audio[7][8]. This helps the model natively generate speech and audio in different contexts out of the box - “Read this in a 1930s radio news voice”.
Limitations & Future Axes of Improvements
Evaluations aligned with real-world use cases
LLM evaluations have evolved from simplistic evals like Hellaswag to MMLU to Humanity's Last Exam[9] to agentic benchmarks like the length of tasks models can complete with 50% success[10]. These agentic benchmarks have provided a continuous axis of improvement for LLMs.
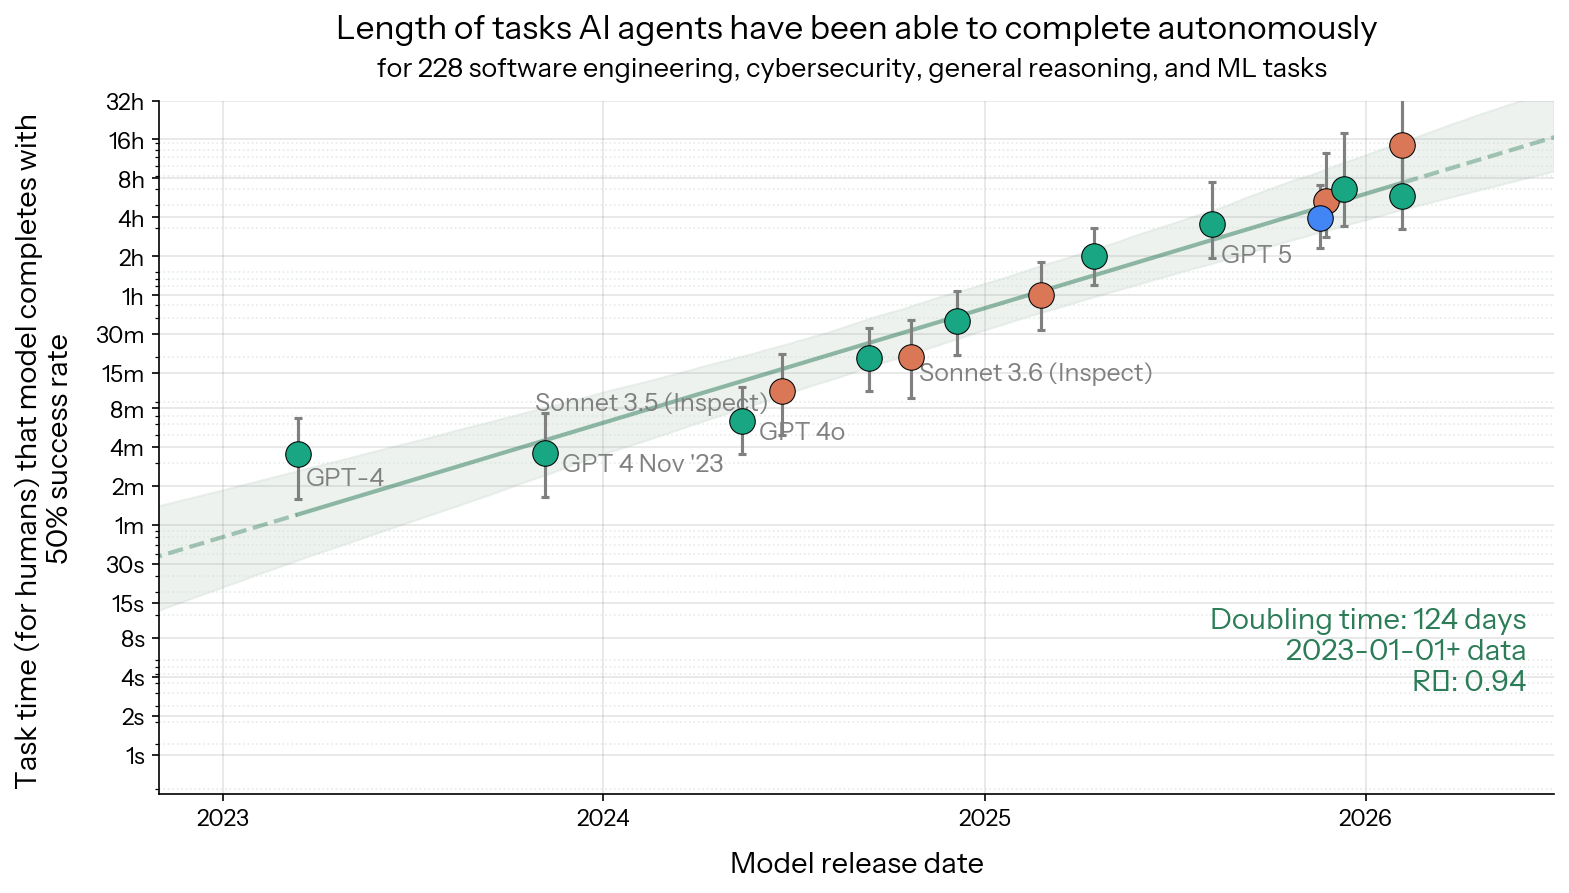
On the other hand, Speech/Audio Models are still stuck at single-turn TTS evaluation[11][12][13] or simple audio understanding benchmarks like MMAU. Despite performing well on MMAU-like benchmarks, models still perform far worse at understanding human emotions & intent from tone[14][15].
Turing Clock: How long does it take for you to realize you are talking to AI?
While we need complex audio understanding benchmarks that require multi-hop reasoning, we propose Turing Clock to evaluate the quality of conversations - how long can a person talk with a model before deducing, reliably better than 50% accuracy, that it's an AI? We expect to report this number for all of our new releases.
Scaling
Despite the model being significantly smaller in scale than current frontier LLMs, the base model shows a real degree of understanding and steerability, but it is still limited in scope. We expect a few OOMs (orders of magnitude) of scaling before the models can predictably show the capabilities we discussed. Scaling requires us to rethink the whole stack - from better non-synthetic data pipelines, to multimodal architecture, better & scale-proof codecs, and scaling audio context from a few minutes to hours.
Post-training
While the base model shows early signs of steerability with pretraining-format prompting, using base models is hit-and-miss. Eliciting behavior with in-context instructions like “add rain, far in the background” requires us to innovate on multi-task instruction-based post-training that is entirely absent in this release.
References
- [1]Nano Banana (Gemini native image generation) · Google DeepMind, 2025
- [2]Crossing the Uncanny Valley of Conversational Voice · Sesame, 2025
- [3]Moshi: A Speech-Text Foundation Model for Real-Time Dialogue · Kyutai, 2024
- [4]Scaling Laws for Neural Machine Translation · Google, 2021
- [5]Emilia: An Extensive, Multilingual, and Diverse Speech Dataset for Large-Scale Speech Generation · 2024
- [6]Robust Speech Recognition via Large-Scale Weak Supervision (Whisper) · OpenAI, 2022
- [7]CTRL: A Conditional Transformer Language Model for Controllable Generation · Salesforce, 2019
- [8]Metadata Conditioning Accelerates Language Model Pre-training (MeCo) · Princeton, ICML 2025
- [9]Humanity's Last Exam · 2025
- [10]Measuring AI Ability to Complete Long Tasks · METR, 2025
- [11]Text-to-Speech leaderboard (controlled voice) · Artificial Analysis
- [12]TTS-Arena-V2 · TTS-AGI, Hugging Face
- [13]Design Arena — audio leaderboard · Design Arena
- [14]Real-Time Voice AI Hears but Does Not Listen · Stanford, 2026
- [15]VocalAffectBench · beSimple, 2026
Cite this report: Prashant Shishodia, Gautam Jha & the Kalpa Labs Team. “Towards Generalist Audio Models.” Kalpa Labs, July 2026. kalpalabs.ai